
During backpropagation, an incoming gradient of 0.6 becomes 0.006 on a negative branch with slope 0.01. That small nonzero value catches my attention because it lets a gradient pass along the negative branch.
Focus on the activation’s output rule, apart from the gradient calculation during backpropagation. Compare the output for a negative input with ReLU’s zero to see how the slope changes the result.
What Leaky ReLU changes on negative inputs
Leaky ReLU is an activation function that returns the input when it is non-negative and a scaled input when it is negative. Its negative branch has slope α, so the function keeps a small, adjustable output where ReLU returns zero.
For input x and a non-negative slope α, the rule is f(x) = x when x ≥ 0, and f(x) = αx when x < 0. With α = 0.2, an input of −5 produces −1, while an input of 5 stays 5.
| Input x | ReLU output | Leaky ReLU output (α = 0.2) |
|---|---|---|
| −5 | 0 | −1 |
| −1 | 0 | −0.2 |
| 0 | 0 | 0 |
| 5 | 5 | 5 |
The existing plot below uses a negative-side slope of 0.2. The positive branch still rises at slope 1, so the coefficient changes only how negative inputs pass through the activation.
Why keep a gradient on the negative branch
During backpropagation, the activation’s derivative scales the gradient passed to the preceding layer. On negative inputs, ReLU’s derivative is zero, while Leaky ReLU uses α.
| Input region | ReLU derivative | Leaky ReLU derivative |
|---|---|---|
| x < 0 | 0 | α |
| x > 0 | 1 | 1 |
This nonzero derivative can let a unit receive a gradient for a negative input where ReLU would pass none through its activation. It does not guarantee that the unit will become useful, that its gradients will be large enough to matter, or that the model’s validation score will improve.
Backpropagation multiplies the gradient arriving from later layers by the activation’s local derivative. For a negative input, an incoming gradient of 0.6 becomes 0.006 when α is 0.01.
The value is nonzero but small, so passing a gradient does not guarantee a useful update.
At x = 0, the two branches meet, but the derivative is not defined by the piecewise function alone. Frameworks choose a boundary convention, so calculations here focus on strictly negative or positive inputs.
Implement the function in Python
A scalar function makes the branch decision visible before it is placed inside a neural-network layer. This version also rejects a negative coefficient, matching the non-negative slope constraint documented by Keras.
Step 1: define the negative branch
def leaky_relu(x, negative_slope=0.01):
    if negative_slope < 0:
        raise ValueError("negative_slope must be non-negative")
    return x if x >= 0 else negative_slope * x
The conditional handles zero with the non-negative branch, and it multiplies only inputs below zero.
Step 2: check values on both sides of zero
I ran the function at its default slope. Inputs −4 and −1 returned −0.04 and −0.01, while zero and positive inputs passed through unchanged.
Step 3: use the same rule for each input
The scalar function handles one number at a time, which keeps the piecewise rule clear. For a tensor or array in a model, use the framework’s activation layer so its automatic differentiation system tracks the operation.
Use the framework’s LeakyReLU layer
Framework layers apply the same negative-branch idea to tensor inputs, but their documented defaults are not interchangeable. Set the slope explicitly when you need the same behavior across frameworks.
| Framework | Layer | Slope parameter | Documented default |
|---|---|---|---|
| PyTorch | torch.nn.LeakyReLU | negative_slope | 0.01 |
| Keras | keras.layers.LeakyReLU | negative_slope | 0.3 |
The PyTorch LeakyReLU documentation gives 0.01 as its default, while the Keras LeakyReLU documentation gives 0.3. Both name the argument negative_slope, so older examples that pass alpha should not be copied without checking the installed API.
Leaky ReLU is a fixed-slope variant. He and colleagues’ PReLU paper describes a related activation whose parameter is learned, which is a different choice from setting one constant negative slope.
The site also has an overview of activation functions and a separate guide to neural networks if you need the surrounding concepts.
Choose the slope with validation results
There is no universal slope that makes a network perform better. Treat α as a model setting, keep the rest of the experiment fixed, and compare the validation metric you chose for the task.
- If negative inputs need a small gradient, test a nonzero slope and inspect the training and validation curves.
- If you want ReLU’s zero output for negative inputs, use a zero slope or the framework’s ReLU layer.
- If the slope should be learned rather than fixed, compare a PReLU layer and account for its additional learned parameter.
A nonzero local derivative addresses one part of the dying-ReLU problem, not every way a unit can stop contributing. Keep the change only if the model’s held-out results support it.
A nonzero slope is a testable choice
Compare slopes on the same inputs before changing a model. The command prints the output lists for 0.01 and 0.1, so the only changed values are on the negative side.
python3 -c "print({slope: [x if x >= 0 else slope * x for x in (-4, -1, 0, 1, 4)] for slope in (0.01, 0.1)})"
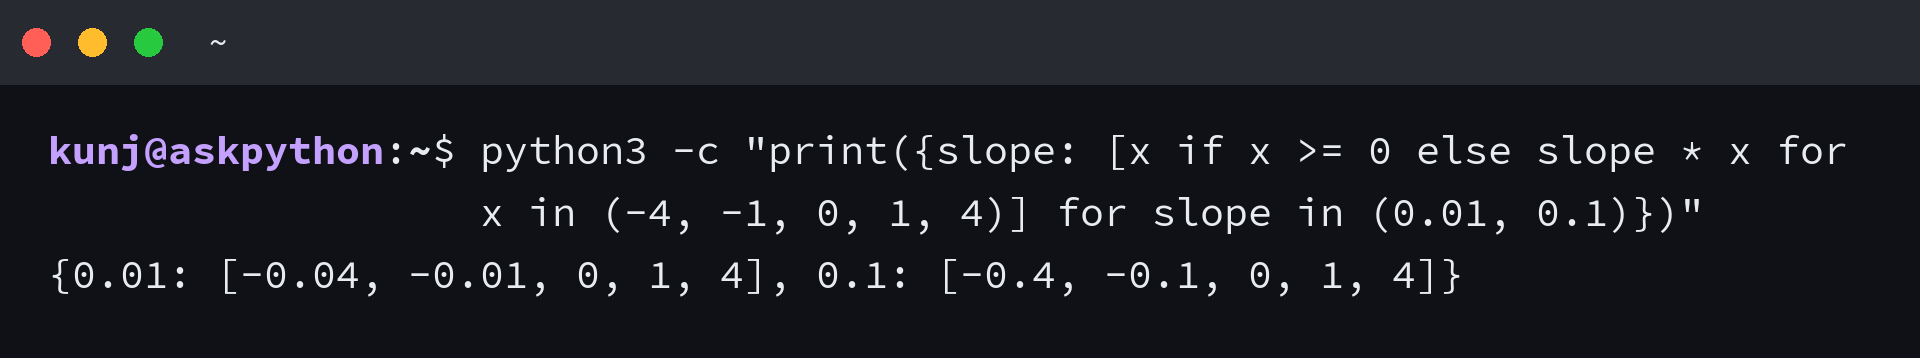
At slope 0.01, inputs −4 and −1 produce −0.04 and −0.01. At slope 0.1, those inputs produce −0.4 and −0.1, while zero and positive inputs stay fixed.
Frequently asked questions
What is Leaky ReLU?
Leaky ReLU returns x for non-negative inputs and α times x for negative inputs. The slope α sets how much of a negative input passes through.
Is Leaky ReLU better than ReLU?
Neither activation is better for every model. Compare them on the same task and keep the one supported by your validation results.
How do you choose a Leaky ReLU slope?
Choose a candidate slope, keep the rest of the training setup fixed, and compare the metric that fits your task. PyTorch and Keras document different defaults, so set the value explicitly when matching behavior matters.
Does Leaky ReLU prevent dying ReLU?
Leaky ReLU gives negative inputs a nonzero local derivative when the slope is positive. That can address ReLU’s zero-gradient branch, but it does not guarantee that a neuron will contribute useful updates or that model performance will improve.
How is Leaky ReLU different from PReLU?
Leaky ReLU uses a fixed negative-slope coefficient. PReLU learns its parameter during training, so the two activations are related but not the same.
