
In Part 1, we saw how ‘Vamana’ represents vectors as nodes, connects them with edges, and uses greedy graph traversal to avoid comparing a query against every vector in the dataset. In Part 2, we investigated how PQ gave us compact representations for inexpensive distance calculations, caching kept useful graph nodes close, how SSDs provided capacity, and beam search allowed multiple promising nodes to be expanded together.
In this last part, we will be exploring how we use the parameters to tune DiskANN.
DiskANN offers several settings that control graph construction and search aggressiveness. Those settings trade recall, latency and memory against one another, There is no correct setting that is universal. It is therefore useful to understand what each parameter changes physically inside the algorithm.
Some parameters affect the graph. Others affect how we search that graph.
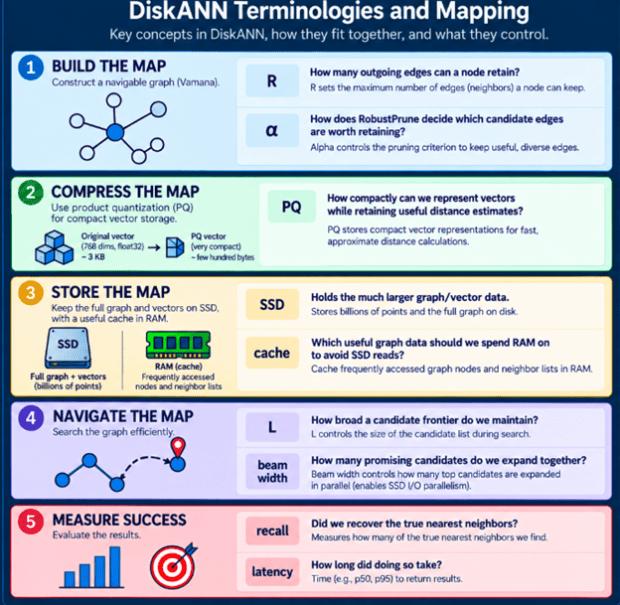
R and alpha shape the map. L and beam width control how we navigate it.
Changing fundamental build parameters such as R or alpha means changing the graph itself, so evaluating them involves rebuilding the index.
Changing L or beam width can change query behavior without rebuilding the graph.
1. R — maximum roads/edges per node
During graph construction, we may identify multiple candidate neighboring nodes, or edges, associated with a given node. We do not need to retain every edge, so (R) sets an upper limit on a node’s outgoing edges—its edge budget.
Larger graphs require more storage, while expanding nodes increases search work. A higher *R* provides richer connectivity and more routes but requires additional index storage and construction time; *R* = 64 does not mean every node has exactly 64 neighbors. It only means pruning allows up to 64 connections per node.
Tradeoffs:
More edges create more routes to search in the vector space, but each route adds computational cost. The larger the search, the longer the index is going to take to build and the longer a query is going to take. The sweet spot is finding enough nodes that add value and make results decent quality wise.
2. Alpha — which roads are worth keeping?
R specifies the permitted number of edges. It does not tell us which ones are useful. That is the job of pruning. Suppose node ‘Waterproof hiking boots have two neighbors’ Rain boots’ and ‘Trail shoes.
‘Rain boots’ is close to ‘Waterproof hiking boots. ‘Waterproof hiking boots’ is also close to ‘Trail shoes. But ‘Trail Shoes’ and ‘Rain boots’ are themselves remarkably close. If we already retain ‘Waterproof Rain boots’ -> ‘Rain boots’ then ‘Waterproof Rain boots’ ? ‘Trail Shoes’ may add little navigational value because ‘Trail Shoe’’s region can already be reached through A. This is the intuition behind RobustPrune.
Rather than simply selecting the R closest vectors, Vamana uses RobustPrune to determine whether candidate edges provide useful routes or are sufficiently covered by edges already selected. The parameter alpha influences this pruning criterion, changing which edges survive and therefore the topology and navigability of the resulting graph.
Trade-off: Changing alpha can produce a more navigable graph and affect recall, but it also changes graph construction and requires rebuilding the index to retune.
3. L — how hard are we willing to search?
Once constructed, the graph is ready for querying.
A query arrives:
“Boots for hiking in the rain” It becomes query vector q, and graph traversal begins.
During the search, we maintain promising candidates – such as below:
P17 Waterproof hiking boots 0.12
P83 Rain boots 0.15
P51 Trail shoes 0.19
P20 Snow boots 0.24
P91 Hiking backpack 0.31
…
Parameter L controls the size of this list. A small L means we are willing to keep a narrow search frontier. A smaller L may limit the list to P17, P83 and P 51.
A larger L keeps more possibilities open, including P17, P83, P51, P20, P91, P33, P74, P82, and others. Greedy graph search can mistake the best immediate direction for the best route. A broader frontier gives the algorithm more opportunities to recover from those decisions.
Trade-offs: Larger L improves recall by exploring more of the graph, but requires more distance calculations, node expansions and potentially SSD reads—raising query latency and resource usage.
4. Beam width — the amount of work issued parallelly.
Assume that *L*, the number of candidates being evaluated, is 100. Our candidate list may contain up to roughly that search breadth. That does not mean we have expanded 100 candidates simultaneously. That depends on ‘beam width’. If beam width = 3, then we may only select 3 candidates out of the list of 100 to expand at any given time. L refers to the number of promising possibilities retained, whereas beam width denotes the number of possibilities expanded simultaneously. SSD performance depends on simultaneous expansion to handle multiple outstanding I/O operations.
DiskANN’s SSD design uses beam search and asynchronous I/O to increase the amount of useful work the SSD can have in flight.
Tradeoffs: Increasing beam width exposes more I/O parallelism, helping DiskANN hide SSD latency. Beyond the SSD’s optimal capacity, larger beams cause unnecessary reads, computation, and I/O contention. The sweet spot is enough parallelism to keep the SSD busy—not maximize parallelism.
5. PQ — required RAM precision
Our original vectors might be large,768 × float32 ˜ 3 KB/vector. PQ can represent them much more compactly for approximate distance calculations. But compression has a cost. More compression can help with smaller in-memory representation and less memory usage. But it also means less precise approximation. This introduces another dimension to tuning. If the PQ representation is too coarse, our approximate distances can become less informative.
Imagine the real distances are:
Waterproof hiking boots 0.121
Rain boots 0.147
Running shoes 0.512
PQ might estimate:
Waterproof hiking boots ~0.13
Rain boots ~0.15
Running shoes ~0.50
Perfect precision wasn’t required. The approximation still clearly tells search which candidates look promising. But aggressive compression can make those approximations noisier.
Tradeoffs: How much RAM are we prepared to allocate to make our approximate distance estimates more informative?
6. Cache — where should we spend our RAM?
PQ helps reduce the amount of memory needed for vector representations, but that does not mean we want to leave the remaining RAM unused. Nodes along frequently used paths are visited more often. Keeping these frequently accessed nodes and their neighbor information cached in RAM can avoid repeatedly fetching them from SSD. A larger cache can therefore increase cache hits, reduce SSD reads, lower I/O pressure, and potentially improve query latency.
Tradeoffs: Caching uses RAM that could serve other purposes. Like the other DiskANN parameters, the goal is not simply to maximize the cache, but to spend the available RAM where it eliminates the most expensive disk work.
7. How these parameters interact
These parameters do not operate independently. For example, increasing L may improve recall but can cause more node expansions and SSD reads. An appropriate beam width may allow some reads to overlap, while increasing the cache size can remove the need for others. Likewise, a larger R may make the graph easier to navigate but gives each expansion more neighbors to evaluate. We are not tuning independent numbers—we are tuning a system.
It is important to work out the right combination of their values, which work well.
8. Recall vs latency — the curve that matters
Suppose exact search for “boots for hiking in the rain” tells us the true top five results for our query:
1. Waterproof hiking boots
2. Tall rain boots
3. Lightweight rain boots
4. Insulated waterproof boots
5. Waterproof trail shoes
With conservative search settings, DiskANN may return:
? Waterproof hiking boots
? Tall rain boots
? Lightweight rain boots
? Hiking shoes
? Winter boots
With three correct of the true five: Recall@5 = 3/5 = 60%
If we increase search effort further, Recall@5 = 4/5 = 80%
If we increase search effort even further, we may get Recall@5 = 5/5 = 100%
But query cost may increase correspondingly with each effort.
“What is the smallest amount of search work that achieves the recall my application requires within its latency budget?”
9. Benchmarking for actual results
A real evaluation also needs a representative query set. For those queries, we establish ground truth—typically using exact nearest-neighbor computation—and then compare ANN results against it. At the same time, measure the operational metrics that matter. Those metrics include –
- Recall
- Latency
- QPS / throughput
- Memory usage
- SSD I/O
- Index size
- Index build time.
The winner is the configuration that satisfies the application’s constraints with an acceptable resource cost.
Summary
The graph gives us a map.
- RobustPrune tries to make that map sparse but navigable.
- R bounds its connectivity.
- Alpha influences pruning.
- PQ gives us compact approximations.
- Caching avoids unnecessary disk access.
- L controls how broadly we search.
- Beam search gives the SSD multiple useful operations to work on.
Using an example –
DiskANN converts “boots for hiking in the rain” into vector *q* to navigate the Vamana graph.
Rather than loading everything from SSD, PQ-compressed vectors in RAM help estimate which nodes look promising, while cached graph nodes avoid disk reads when possible. The most promising candidates are retained in list *L*, while the beam width specifies the number of candidates expanded at each stage.
Only nodes deemed promising are selectively retrieved from the SSD. The candidate list grows by adding neighboring items until convergence, finding similar products—such as waterproof hiking and rain boots—without comparing every dataset vector.
The goal is not to make searching for a billion vectors cheap by making every comparison faster. It’s to design the index so that we don’t need to make most of those comparisons in the first place.
In the next post, we will look at how SQL Server uses this algorithm for vector search and what we can do to understand that better.
